Adding memory to an agent feels like an obvious improvement. If a coding agent has seen the same bug before, why should it make the same mistake again? If a repository has a preferred workflow, why repeat the explanation in every session?
Recent research gives a more useful answer: memory can improve an agent, but only under the right search pattern and scope. The question is not whether an agent should remember more. It is which memories should shape the next decision, and which ones should stay out of the way.
When memory helps—and when it narrows the search
A Findings of ACL 2026 paper studies dynamic coding memory in two kinds of machine-learning engineering agents. One is a sequential agent that repeatedly debugs and refines a solution. The other is a tree-search agent that explores several solutions in parallel.
The result is not a simple win for memory. In the sequential setting, memory helps avoid recurring mistakes and connect a new change to earlier attempts. In the exploratory setting, the same stability can become a constraint: past procedures reduce search diversity and move the agent toward a familiar answer too early.
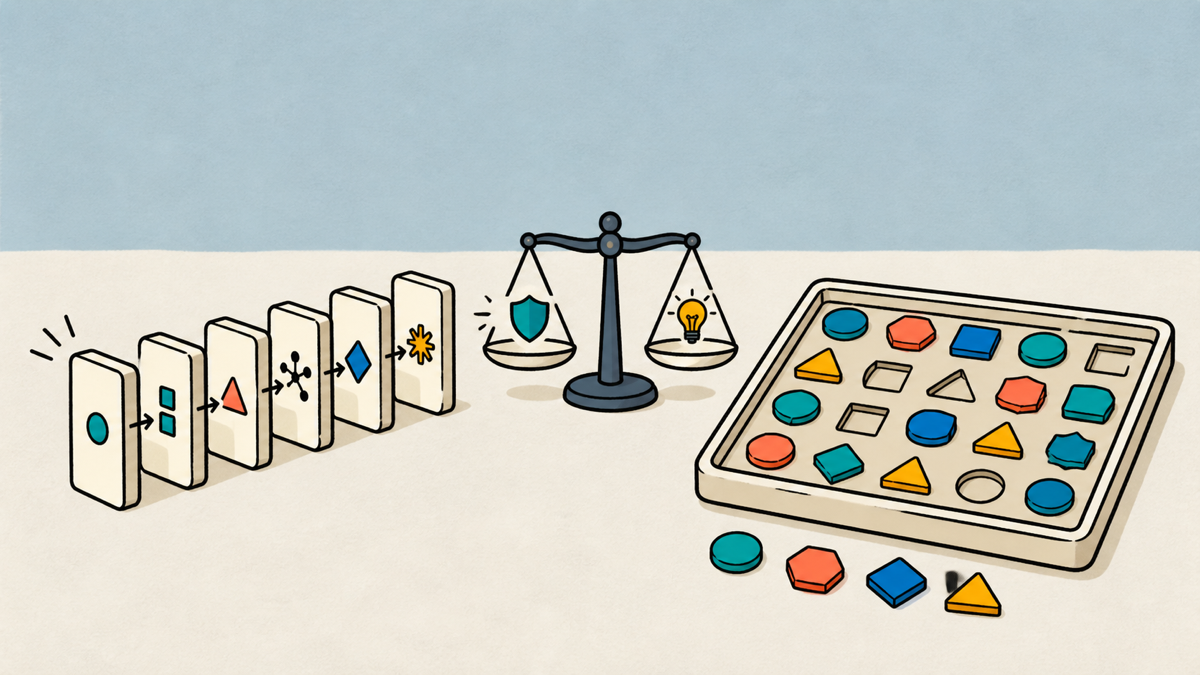
The memory useful for a repeated repair is not automatically useful for an open-ended search.
This distinction matters in practice. A record of how one test failure was fixed can help when the same component breaks again. It can hurt when an agent is investigating a new architecture and treats the old fix as the default shape of the solution. Reliability and discovery are different objectives. A memory layer that optimizes only for fewer repeated errors can quietly make new solutions harder to find.
Context files have a cost too
The same tension appears in repository-level instructions. An ICLR 2026 workshop paper from ETH Zurich and SRI evaluated AGENTS.md-style context files across coding agents and language models. In the tested settings, the files did not improve task success while increasing inference cost by more than 20 percent.
The study also found that agents generally followed the instructions. That is precisely why unnecessary instructions matter. An agent can spend more tokens reading files, running checks, or satisfying requirements that do not apply to the current task. Compliance is not the same as usefulness.
This does not mean AGENTS.md is useless or that all context files should disappear. The narrower lesson is more practical: human-written context should keep stable requirements and remove historical preferences, speculation, and reminders that do not change the current decision.
A bounded default is one answer to the trade-off
This is the design constraint I chose for Luthn. Its default auto-recall does not search the private store on every turn. At the start of a new task or material topic, it requests at most three items, uses an estimated 600-token budget, has a 200-millisecond fail-open deadline, and reuses the result for ten minutes.
Those numbers are not a universal memory recipe. They are a deliberately small default that makes recall useful without making every turn carry the full history of a project. The same system also scopes recall with non-sensitive project, task, and topic keys, and applies classification and safe-projection rules before an item becomes agent-visible.
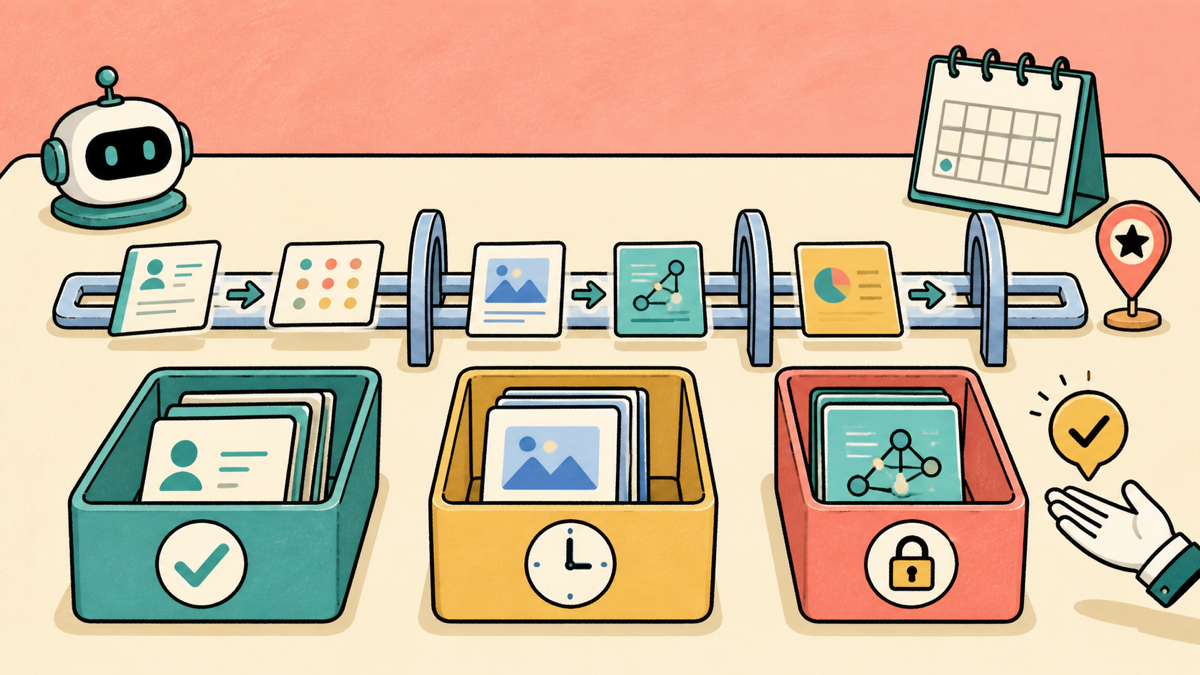
Memory becomes easier to operate when validity, expiry, and access are visible decisions.
A bounded context pack also changes the failure mode. If the lookup is empty or unavailable, the agent does not receive a guessed replacement. It continues without unverified context or reports that the context could not be confirmed. That is less convenient than unlimited recall, but safer than turning an old record into an invisible premise.
Memory needs types and boundaries
A useful memory system should separate at least four kinds of information. Procedural memory describes a method that worked before. Project state describes what is true about a repository or task at a particular time. Preferences describe how a person or team wants work to be done. Evidence and hypotheses describe what is known, uncertain, or still awaiting confirmation.
These categories should not share one retrieval rule. A verified build command may be safe to reuse automatically. A temporary project decision may need an expiry date. A user preference may apply only to one owner or workspace. An inference should be shown as an inference instead of being promoted to a fact just because it was retrieved often.
Metadata is part of the memory, not decoration around it. The system needs to know where a record came from, when it was last confirmed, which project or task it belongs to, how sensitive it is, and what happens when it expires or conflicts with a newer record. It should also be possible to tell whether a retrieved memory influenced an answer or tool action.
What this article measures—and what it does not
The research claims above come from the cited studies. The Luthn limits come from its public documentation. I am not presenting a controlled local A/B experiment that proves one memory configuration is best. That experiment still needs to fix the task, model, and budget before changing the memory layer.
| Comparison | Record |
|---|---|
| No memory vs bounded memory | Success, recurring errors, correction count |
| Small pack vs large pack | Token use, latency, irrelevant context |
| Memory on vs memory withheld | Search diversity and time to first viable solution |
| Fresh vs stale record | Whether the agent notices and recovers from outdated advice |
| Conflicting records | Whether the conflict is shown or silently resolved |
The point is to measure what memory changes, not to reward the memory system for retrieving more. Long-term memory is a policy for allocating an agent’s limited context and attention. Good memory carries hard-won knowledge forward. Good boundaries keep that knowledge from becoming an invisible assumption in every new problem.
The next step for agent memory is therefore not remembering everything. It is knowing when not to remember, when not to retrieve, and when to ask for confirmation.